NeoMME: open models that search scanned documents as images, no OCR needed
Two small, freely licensed models released on Hugging Face search PDF pages by how they look, and the smaller one runs about twice as fast as a close rival.
By Eric Powlesland 3 min read
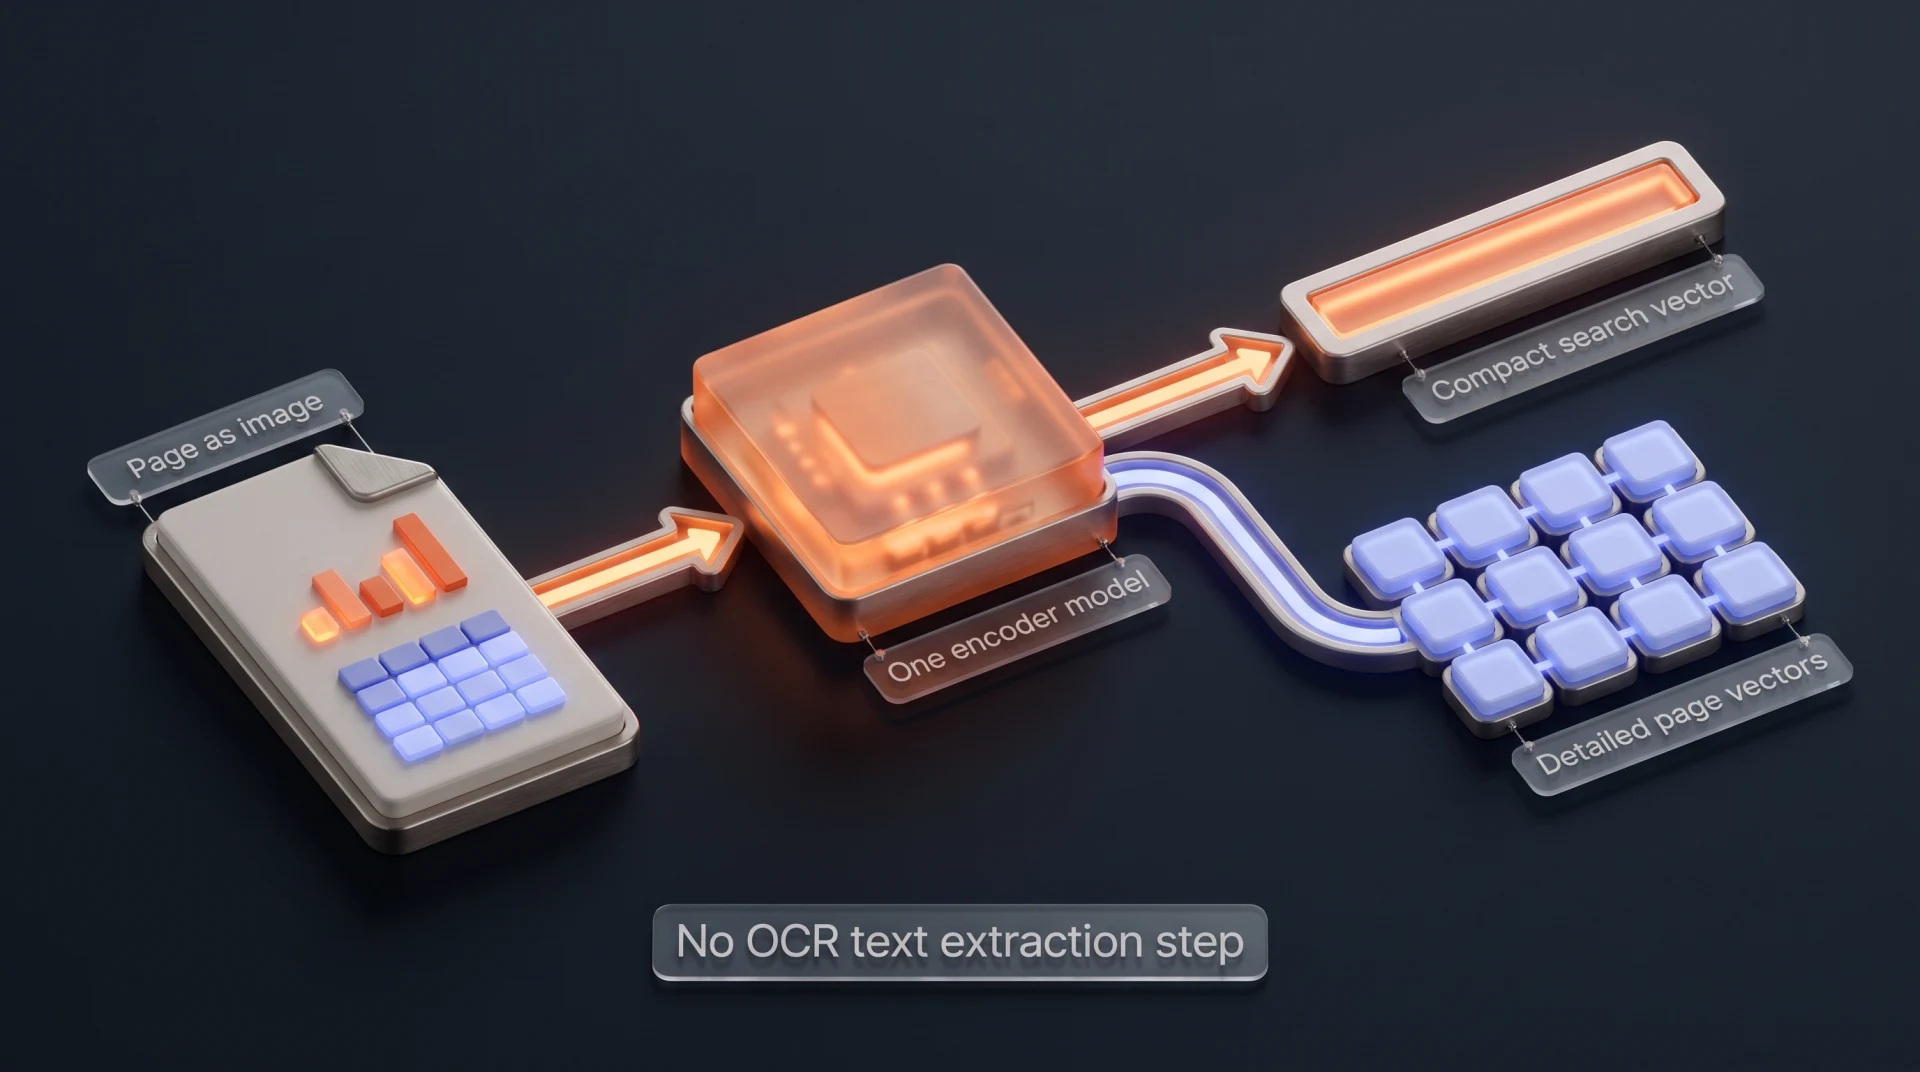
A new family of open AI models called NeoMME is built to help software find the right page in a pile of documents. It does this by treating each page as a picture instead of first converting it to plain text. The models come in two sizes, 260 million and 800 million parameters. Both are small by current AI standards and are released under the permissive Apache 2.0 license.
As the Hugging Face Blog reported, the work began as a side project between two friends. H Company supported it and supplied the computing power for training. Most document-search models are adapted from larger AI systems that generate text, and they bolt a separate image component onto a language model. NeoMME uses one model, trained from scratch, that reads text and image patches together. It handles many languages and can take in high-resolution pages without shrinking them.
The team also fine-tuned a search version called NeoMME-Retriever. On a standard document-retrieval benchmark, ViDoRe v3, the 260M version scored within a hair of a model about 14 times its size. It also scored highest among the models tested that are under 800 million parameters. On a single NVIDIA L40S graphics card, it processed about 51 large pages per second, nearly twice the 26 pages per second of a comparable model, ColModernVBERT.
What it means for your business
Many businesses keep important information in PDFs that hold tables, charts, forms and scanned pages. Text-based search often loses that structure, because extracting text from a PDF flattens layouts and can miss what is inside a chart. Searching the page image keeps those visual cues. It also skips the optical character recognition (OCR) step that tools normally run first.
This approach can be the first step in a system that answers questions from your own documents. The system finds the most relevant pages, then passes the page images to an AI model that can read them and write a response. NeoMME is one of the building blocks for that kind of setup, not a finished product you can install.
Three practical points stand out:
- Cost. Smaller, faster models mean less time renting graphics hardware to index a document library. They also make it cheaper to add new files later.
- Storage. Detailed page-level search indexes can be large, about 1.5 MB per page on average in the team's tests. Using compression, they cut that to 39 kB per page while keeping over 99% of search quality. A more aggressive setting reached 6 kB per page, 255 times smaller, with over 95% of the quality.
- Licensing. Apache 2.0 allows commercial use, which lowers the barrier for software vendors and in-house teams to try it.
The honest caveat: these are results reported by the people who built the models, measured on public benchmarks. How well it handles your own invoices, contracts or manuals is not yet known. Putting it to work also takes developer effort, including a database for the search index and a separate AI model to generate answers.
What to watch
The models are available now through Hugging Face's widely used Transformers software, and there is a public demo for trying document question-answering. Independent testing on real business documents will show whether the speed and storage gains hold up outside the lab. If you already use or plan to build a document search or internal Q&A tool, ask your developer or vendor whether page-image search fits your files. It is most likely to help where documents are heavy on tables and charts.