Allen Institute releases Olmo-core 3, open software for training very large AI models
The open-source framework behind the next Olmo model is built to train mixture-of-experts AI systems efficiently, with tests reaching past one trillion parameters.
By Eric Powlesland 3 min read
The team behind the Olmo family of open AI models has released Olmo-core 3, a new version of the software it uses to train large language models. The upgrade centers on a rebuilt system for training mixture-of-experts (MoE) models and is published openly for anyone to use. The announcement appeared on the Hugging Face Blog under the Allen Institute for AI's account.
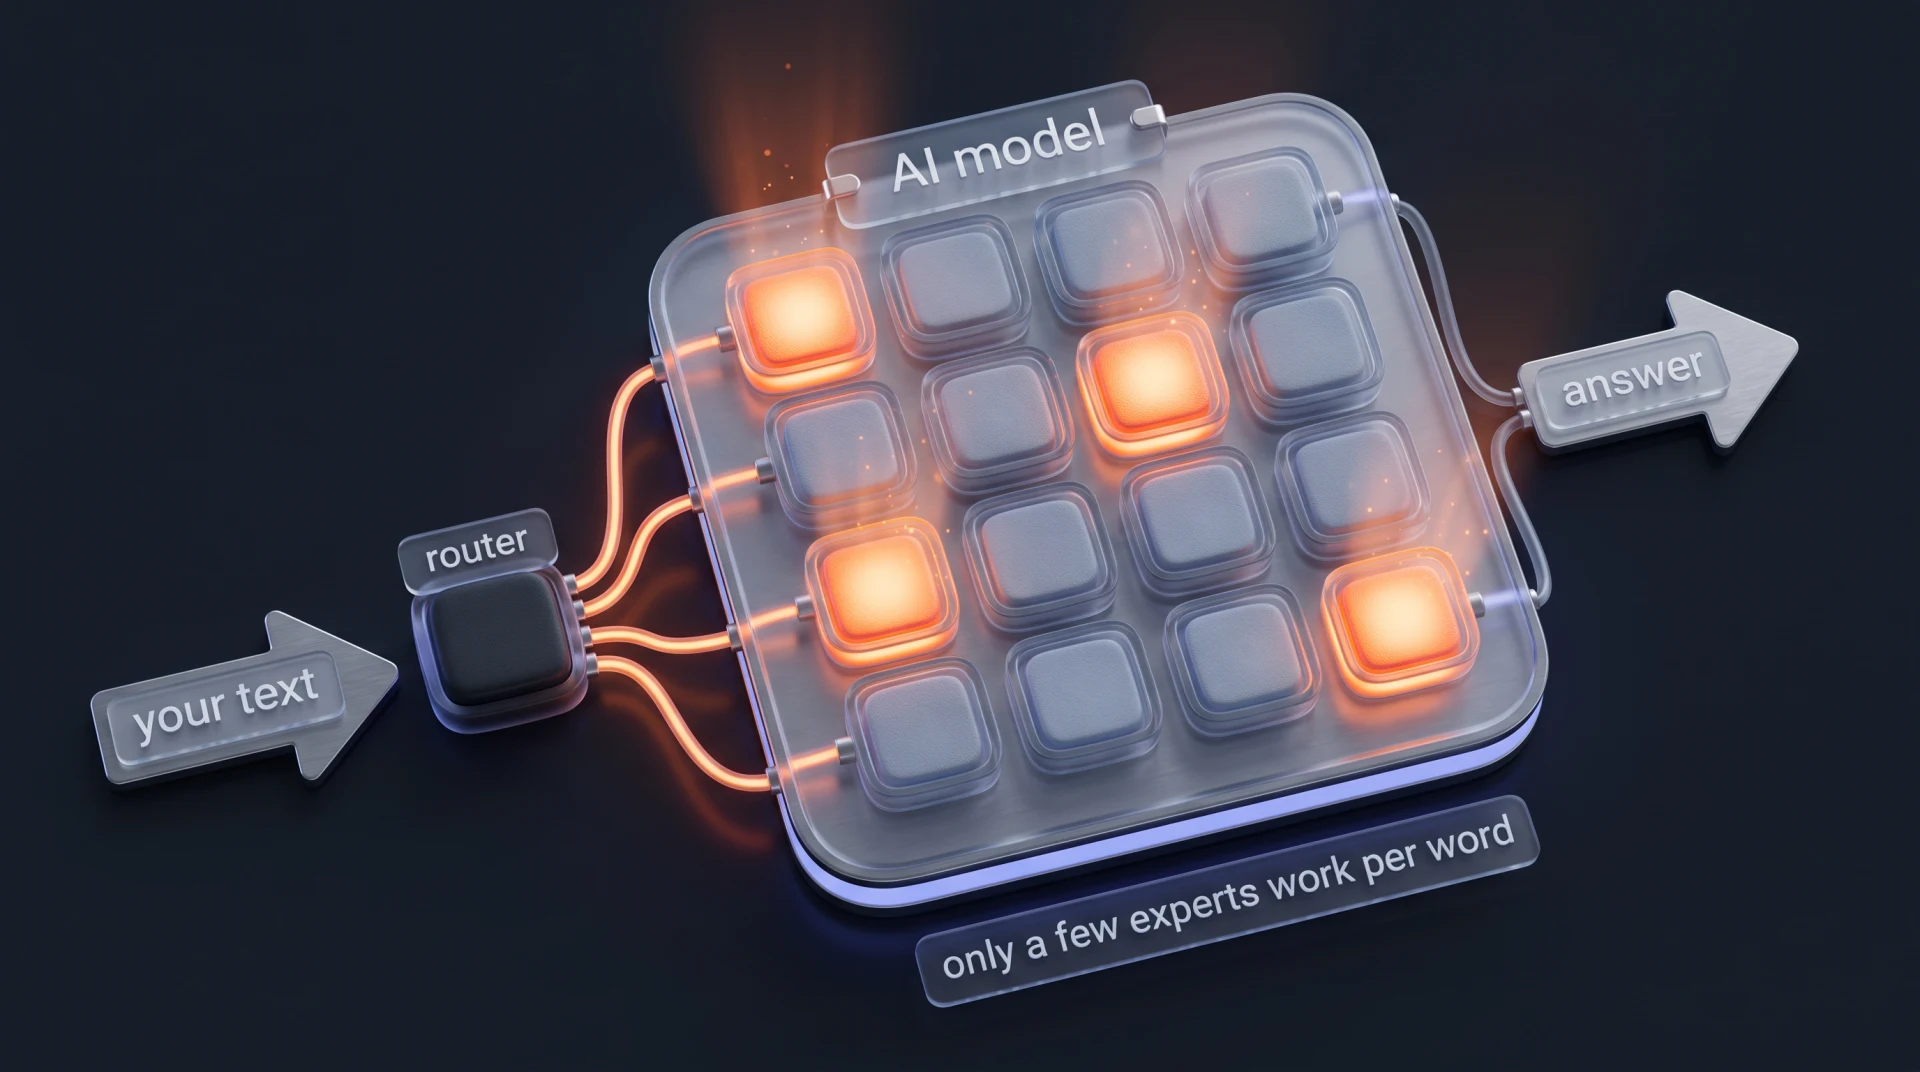
An MoE model is split into many specialized sub-components, called experts. For each piece of text, only a few experts do the work. This lets a model hold far more learned knowledge without the cost of running the whole thing every time. The catch is that the full model still has to sit in GPU memory, and sending data to the right experts across a cluster of machines adds overhead. As models grow, that overhead can eat up the savings.
Olmo-core 3 is designed to reduce that overhead. In one test, the team grew a model's expert pool from 8 to 128 while still using four experts per piece of text. Total model size rose from 4.6 billion to 47 billion parameters, and training speed dropped by less than 5%. On eight NVIDIA B300 GPUs, a 47-billion-parameter model trained at about 2.7 times the speed of the team's earlier setup: 52,000 tokens per second per GPU versus 19,400.
The team also reports benchmarking a 1.2-trillion-parameter configuration on 512 GPUs, and a short test reaching 2.38 trillion parameters. These tests measured system performance, not the quality of a finished model. A lower-precision number format called MXFP8 raised training speed by about 21% in a controlled test and modestly cut memory use.
The accompanying technical report also covers what did not work. One finding, which the team calls "token gerrymandering," describes a scoring method meant to keep work evenly spread across experts that could look better even as the real workload became more lopsided. Another found that running communication and computation at the same time sometimes slowed training down.
What it means for your business
For most small and mid-sized businesses, the direct impact is small. You are not going to train a trillion-parameter model, and this is infrastructure software for research labs and AI developers.
The indirect effects are worth understanding, though:
- Open models may get more capable. The team says the next Olmo model will use this MoE design and aims to be its most capable yet, trained on its largest dataset with its longest context window. More capable open models give businesses more options beyond the major commercial AI providers.
- Training costs matter to your costs. Expensive training is one reason advanced AI has been concentrated in a few large companies. Tools that make training more efficient, and that are shared openly, can widen the field of model builders over time. More competition tends to help buyers.
- Transparency has practical value. The team's argument is that open weights are more useful when the training process behind them is open too. If your business cares about knowing how an AI tool was built, for compliance or trust reasons, fully open projects like Olmo are easier to evaluate than closed ones.
None of this changes what you should buy or build this quarter. It is a signal about where open AI development is heading.
What to watch
The source does not give a release date for the next Olmo model, and the trillion-parameter results are performance tests rather than trained models. The real measure will be how well the next Olmo performs once it is out, and whether other labs adopt Olmo-core 3 to build their own open models. If you use or are considering open-weight AI models, that release is the one to keep an eye on.